Seven Ways SitecoreAI Agent Workflows Fail in Production—and How to Design Around Them
A workflow can produce convincing copy and still leave the wrong page changed, an approval disconnected from the final revision, or an external action in an uncertain state. Those are the failures to design for before giving an agent responsibility for production work. A good demonstration shows that the agent can complete a task. A production design should also explain what happens when inputs are ambiguous, a dependency fails, or a person changes the content while a run is waiting.
The seven failure modes below are architectural risk scenarios, not a report of seven confirmed Sitecore incidents. They combine documented SitecoreAI behavior with proposed engineering controls. The examples are illustrative. No customer outage, measured performance improvement, or implementation experience is invented. Where a control requires a custom integration, persistence layer, or operator procedure, the article says so. Treat the sample records as design artifacts rather than importable Sitecore configuration.
Sitecore distinguishes standard agents, which can choose how to execute instructions, from workflow agents, which define an execution path. Its documentation recommends workflow agents for processes needing checkpoints and for consequential actions that should not repeat on retry. That distinction is a useful starting point, but it does not establish the transaction guarantees of every downstream integration. Review the actual tool and API contracts before assigning recovery responsibilities. See Sitecore’s agent selection guidance.
My design preference is to give the model freedom inside a bounded drafting task and keep production state transitions explicit. That adds orchestration work. It also gives an operator a concrete answer to “what may happen next?” rather than asking them to interpret a long conversation. A team could reasonably choose greater autonomy for disposable drafts. For a workflow that modifies shared content or triggers another system, I would require evidence at each consequential boundary.
Consider a hypothetical campaign workflow throughout this article: it receives a brief, selects a site and language, retrieves source material, creates a localized draft, sends it for review, and eventually hands it to the publishing process. The objective is an approved, correct destination artifact. The objective is not merely a completed generation step. Each section describes how that workflow could fail, a proposed control, and a practical exercise to expose the weakness before release.
1. The agent works from the wrong context
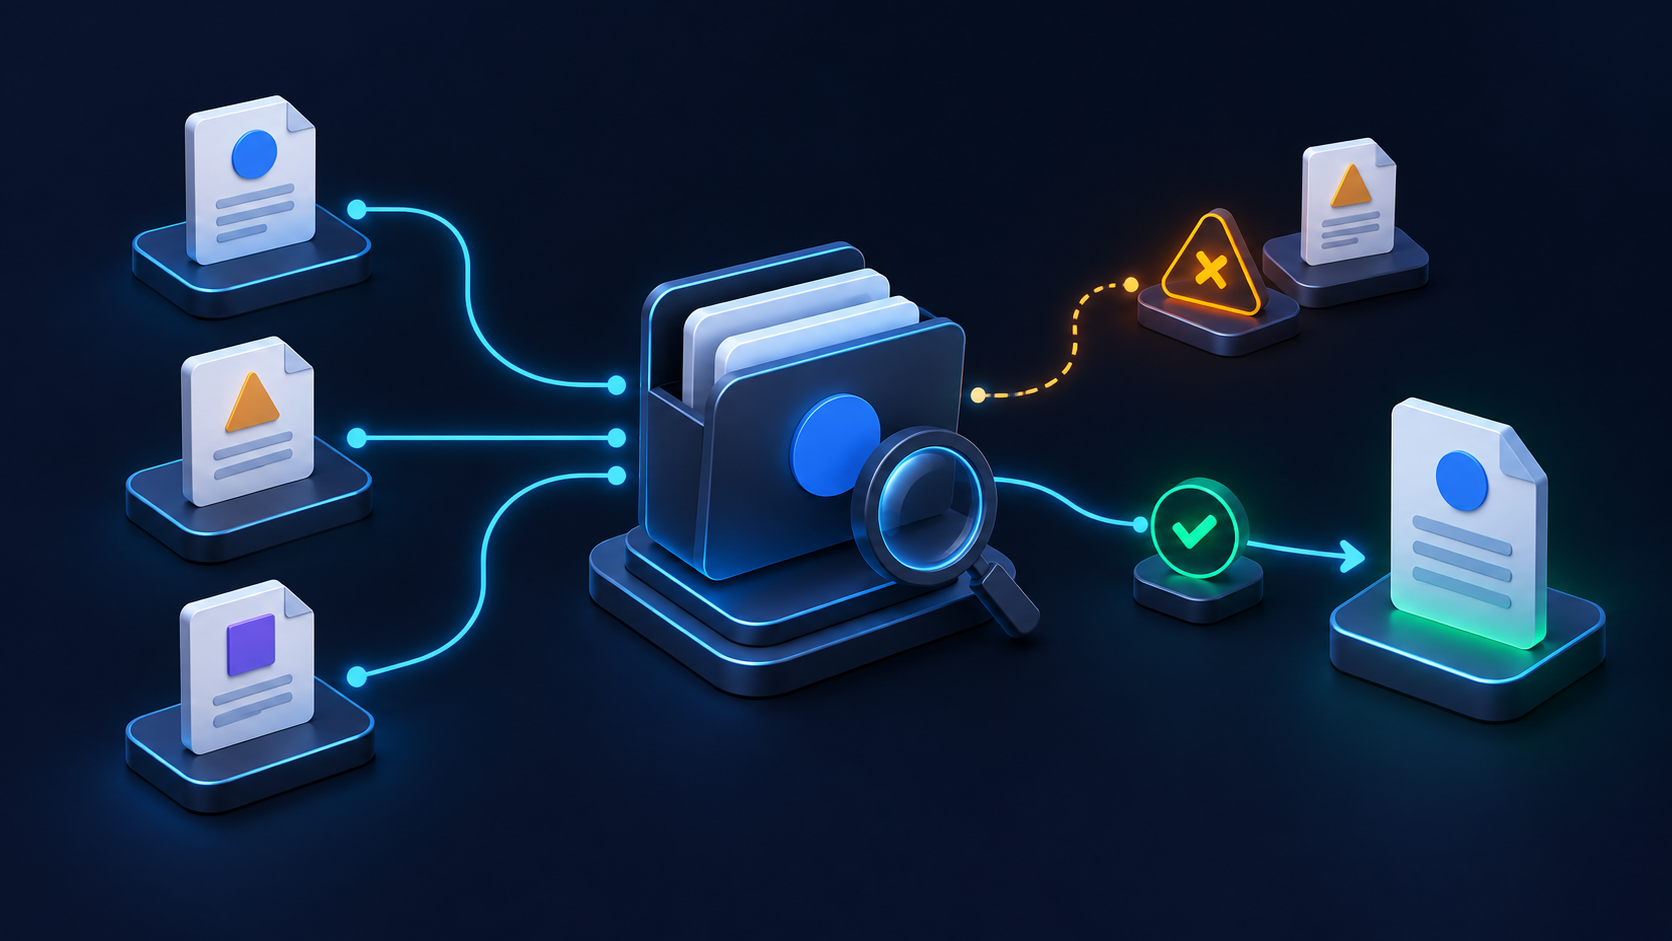
The failure: a plausible answer for the wrong destination
In the campaign example, suppose a brief says “refresh the product page for the autumn launch.” The organization has several sites, regional variants, and similarly named products. A dangerous implementation resolves the first plausible page and starts writing. The wording can look polished even though the selected page belongs to another market. Treat this as an input-resolution failure. Improving the writing prompt does not establish which destination the user intended, so the proposed workflow should resolve that destination before generation begins.
Sitecore’s brand context documentation describes editable information about audiences, offerings, messaging, content guidelines, and customer evidence. It also supports multiple brand contexts. The application guidance explains that users select a context and the agent determines relevant information within it. These are useful grounding capabilities; they are not proof that a particular campaign brief selected the correct context. Review both Brand context and applying context in Agentic studio when designing the input stage.
The design: resolve identity before generating language
I recommend a small context manifest owned by the integration or campaign process. Record the organization boundary, destination site, language, target item identifier, approved source references, and the relevant campaign date. Include the brand context identifier or a traceable reference where the available interface exposes one. These are proposed application fields, not a promise about a native Sitecore object. Their purpose is to turn assumptions into values that a reviewer and a validator can inspect independently of the generated prose.
Require the workflow to demonstrate that the target matches the requested site and language before allowing a write. If a search returns several credible candidates, send that ambiguity to a person or a separate resolution step. Do not ask the drafting model to silently select whichever result makes the task easiest. Likewise, define what “missing language” means for your process. A workflow may request clarification, stop, or create a proposed translation task; it should not quietly treat another language as equivalent to the requested destination.
Give sources an explicit authority order. For this illustrative campaign, an approved product specification could outrank old campaign copy, while an approved regional terminology sheet could govern local wording. The organization should decide that order and document exceptions. When sources disagree, retain the conflict in the review packet. Do not let the agent merge incompatible claims into one confident paragraph. A useful draft can say that a fact requires confirmation. An apparently complete draft that conceals the conflict is harder to review responsibly.
Separate reusable context from run-specific instructions. A brand guide may remain relevant across campaigns, while a temporary offer or launch restriction belongs to a particular run. Attach an owner and a review date to each important source in your own manifest. If you preserve a source snapshot, apply your normal access and retention rules. The recommendation is to preserve enough provenance to explain a decision later, not to make permanent copies of every document the organization can access.
A concrete acceptance exercise
Build an illustrative fixture containing two sites with the same page title, two language variants, and an obsolete campaign brief. Ask the workflow to draft for one named market. The acceptance condition should include correct destination selection and correct evidence selection, not just readable text. Then remove the market from the request. The expected behavior should change to an explicit ambiguity outcome. A system that makes the same confident selection in both cases has not demonstrated that it respects the missing information.
Use this proposed manifest as a discussion artifact during implementation. The strings are placeholders and the structure belongs to your application. Decide which values must be resolved by trusted code, which can be suggested by the agent, and which require a campaign owner. Do not confuse a model-generated field with a verified fact simply because the field is present.
{
  "campaignKey": "illustrative-autumn-launch",
  "target": {
    "site": "approved-site",
    "language": "approved-locale",
    "itemId": "resolved-item-id"
  },
  "sourceRevision": "reviewed-source-reference",
  "contextDecision": "verified",
  "unresolvedQuestions": []
}
The practical tradeoff is preparation time. Someone must maintain source ownership and resolve ambiguous requests. My preference is to pay that cost before generation, because a correct draft for the wrong market still requires rework. Start with the smallest useful manifest rather than a large knowledge-management project. Require a destination, a language, an evidence reference, and an explicit unresolved state. Add fields when a real review or recovery question shows that the current record cannot explain the run.
2. Tool outputs are mistaken for reliable contracts
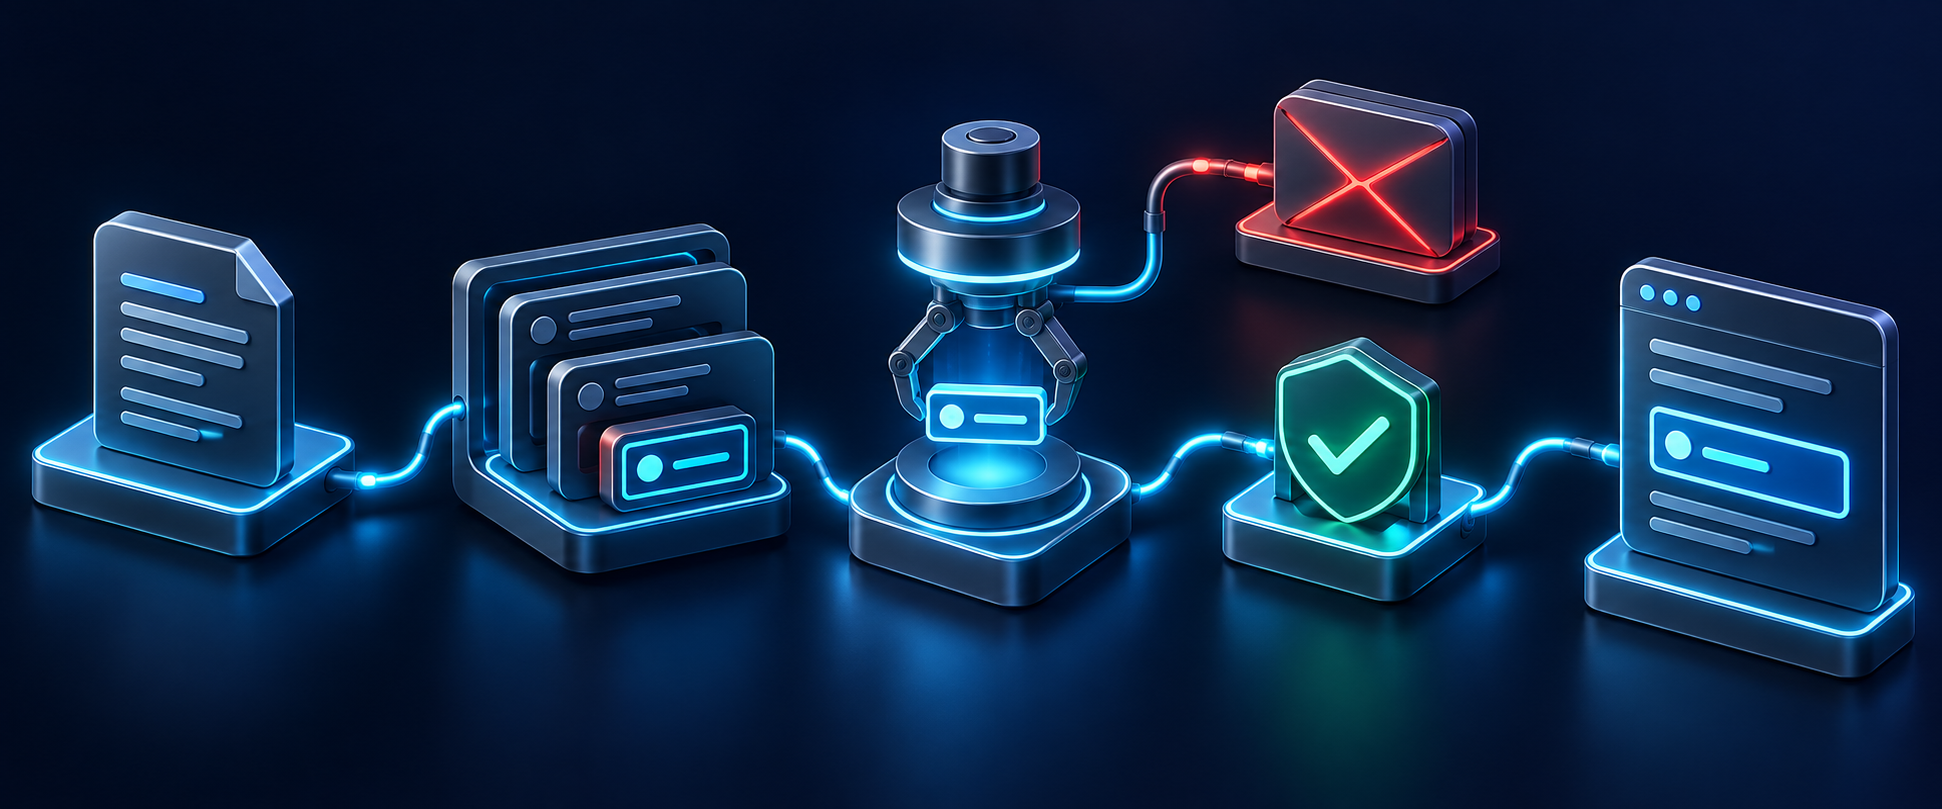
The failure: the next step receives the wrong shape
Imagine the page search succeeds but the next action receives the entire response object instead of one page identifier. Another possible implementation reads an identifier from the wrong search result. In both cases, the orchestration may look connected on the canvas while the data contract is wrong. The failure is at the boundary between steps. The proposed remedy is to inspect the actual response, normalize the required fields, and validate their meaning before allowing them to drive another operation.
Sitecore’s Invoke Tool documentation makes this boundary concrete. Responses can contain success indicators, errors, warnings, and nested data. Its example passes a search result’s item identifier into a page-content request and warns that the exact field path can vary. It also documents separate tools for reading content, changing content, changing layout, and inspecting rendered output. The lesson is to verify the selected operation and the exact value it receives, rather than copying an example expression as a universal contract.
The design: introduce an explicit adapter boundary
For custom integrations, define a narrow internal record between a tool response and the business workflow. The adapter should extract the destination identifier, source language, applicable status, and any evidence needed for the next decision. Preserve a reference to the original response for diagnosis, subject to redaction rules. Reject missing or unexpected values. If you cannot reliably distinguish a valid result from an error envelope, stop before the next write. A well-formed JSON document is only the beginning of this check.
Validation should include semantics as well as types. A nonempty string can satisfy a primitive schema while identifying the wrong item. A result collection can be syntactically valid while containing no approved match. A success flag can accompany warnings your campaign policy considers blocking. Define these interpretations outside the drafting prompt. That makes them reviewable by the people responsible for the integration and avoids asking another generation step to guess whether the previous one really achieved the business requirement.
Keep each action’s responsibility small enough to inspect. A resolution action should identify the target. A read action should retrieve the material needed for the proposed change. A writing stage should produce a candidate patch or draft. A validation stage should decide whether that candidate is eligible to proceed. These are architectural responsibilities, not instructions to create undocumented Sitecore action types. Implement them with supported workflow actions and, where necessary, a service you own. Document which component enforces each condition.
Distinguish an operation response from the desired postcondition. For example, your adapter may record that a request was accepted, while a later read verifies that the intended field actually contains the approved text. Do not label both states “done.” Choose names that tell an operator what evidence exists. If the interface only confirms receipt, retain a state such as accepted or awaiting verification. The final business state should be assigned only after the specific evidence required by your process has been checked.
A proposed normalized record
The following object illustrates an integration-owned boundary. It is not Sitecore’s response format. Its value is the distinction between a selected target, an accepted action, and a verified result. A team can simplify it for a draft-only workflow. A workflow that writes shared content should explain how each state is reached and what prevents a later action from treating an unverified response as permission to continue.
{
  "operationKey": "campaign-item-locale-change",
  "targetItemId": "verified-target",
  "result": "awaiting_verification",
  "providerResponseRef": "restricted-response-reference",
  "warnings": [],
  "postconditionVerified": false
}
Test this boundary with fixtures that include an empty result set, several plausible matches, a failure envelope, and a success response with a warning. Include a fixture where a nested property moves or is absent. The expected result is an understandable contract failure, not a fallback to an arbitrary value. These tests are useful because they check the integration’s decision at a consequential boundary. They should not merely reproduce the same field-path expression used by the implementation and declare it correct.
The tradeoff is maintenance. An adapter is another component that must evolve with the interface. Keep the record small, retain representative sanitized fixtures, and assign ownership when the workflow is released. Resist the temptation to normalize away uncertainty. A field such as “target not uniquely resolved” is operationally valuable. The point is to make provider variation manageable while preserving the facts that determine whether the business action is safe to perform.
3. Retries repeat actions that already happened
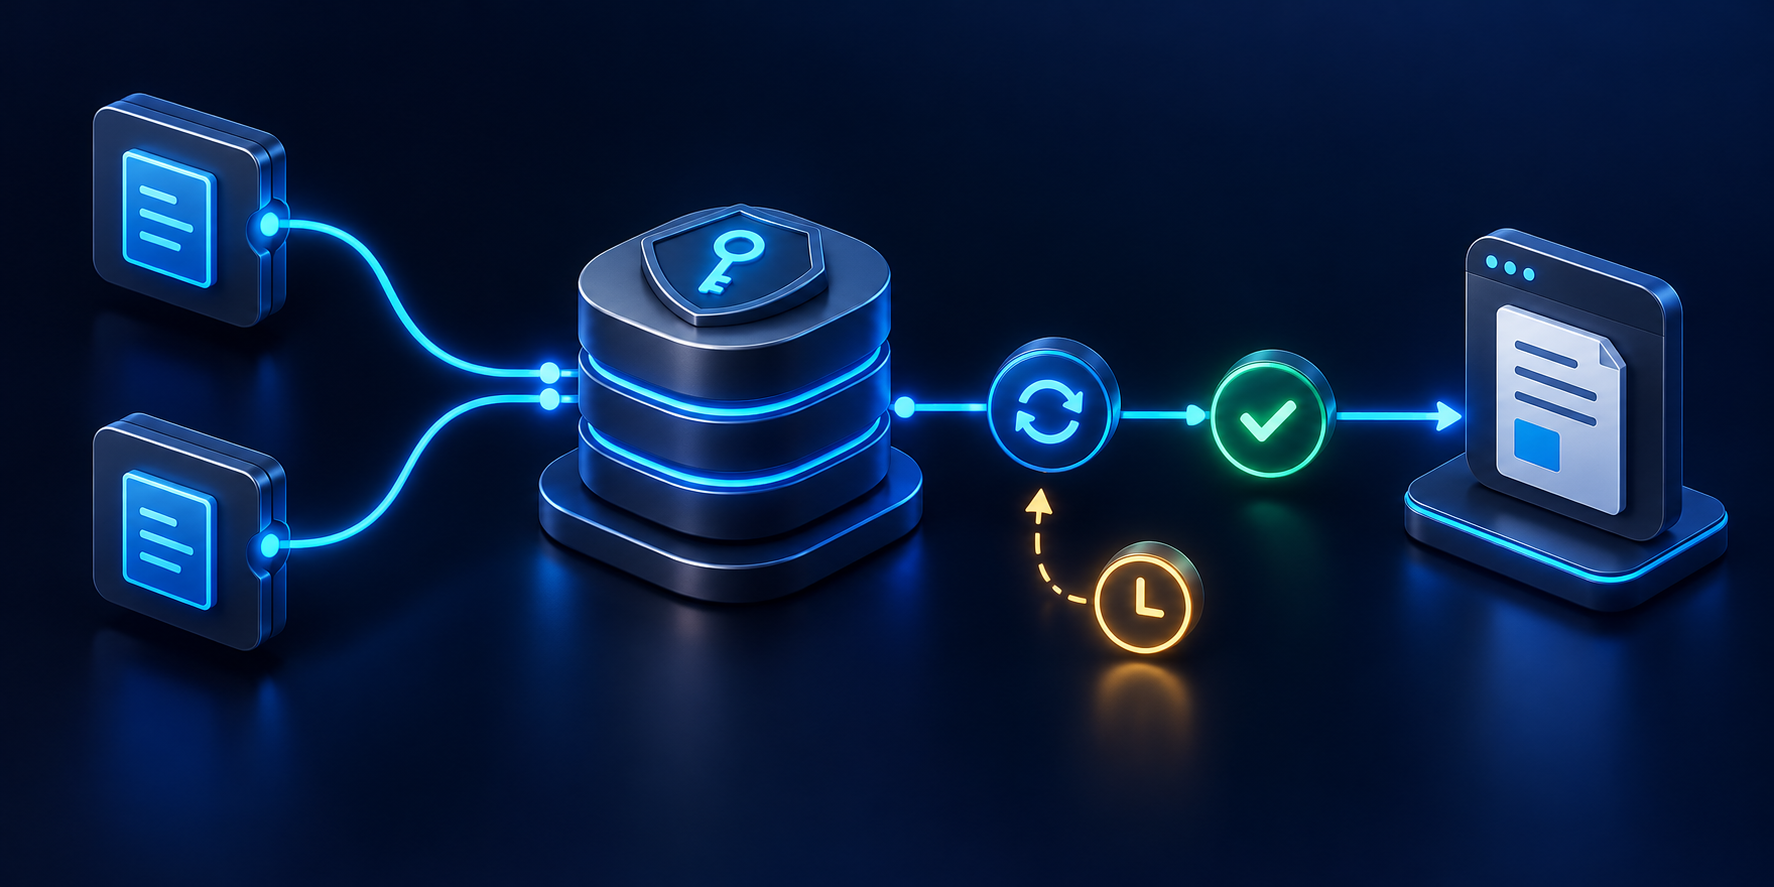
The failure: a timeout becomes a duplicate business action
In the hypothetical campaign, an integration sends a request to create a draft. The caller loses the response. An unsafe recovery restarts the entire workflow, including creation and a later notification. The risk is that the first request completed even though the caller did not observe its result. Treat an uncertain outcome as a distinct condition. It is not evidence that nothing happened, and it is not enough information to choose a blind repeat of a consequential operation.
The distributed-systems principle is established in the Amazon Builders’ Library discussion of idempotent APIs: retries need a way to recognize the same intended request and avoid additional side effects. That source describes AWS design patterns, not Sitecore guarantees. Sitecore’s workflow-agent guidance discusses checkpoints and resumption, but you still need to establish what happens at each external write boundary. A resumable workflow should not be assumed to make every called system idempotent.
The design: preserve intent and reconcile uncertainty
Assign an operation identity before issuing a consequential request. In a custom integration, derive that identity from stable business intent, such as the campaign, target item, locale, and approved change revision. Do not generate a fresh identity every time the transport retries. Also do not collapse two intentionally different changes into one identity merely because their text happens to match. The deduplication decision should represent what the user authorized. Document how long that identity remains meaningful for the downstream system.
If the provider supports a documented idempotency mechanism, use its exact contract and confirm its retention and conflict behavior. If it does not, your integration may need a durable operation ledger plus a reconciliation procedure. Record the intent before calling the provider and preserve the returned identifier when available. Be candid about the limit: a ledger alone cannot guarantee at-most-once effects across an arbitrary remote system when a process crashes between the remote action and the local record update.
Define recovery for that gap rather than hiding it. A reconciler might search for a previously created artifact using a supported stable reference, inspect its destination and revision, and then link it to the operation record. If reliable correlation is unavailable, route the outcome to an operator. Do not deduplicate solely by a human-readable title that several drafts could share. The goal is to establish whether the authorized effect exists, not merely whether something similar can be found in the destination system.
Separate drafting recovery from action recovery. A failed content-generation step may be eligible to run again, while a completed notification should stay completed. Preserve checkpoints at boundaries that matter to the business. Decide whether a resumed run may reuse an earlier generated artifact or whether changed evidence requires a new revision and approval. A retry must not silently change the content being enacted under an old operation identity. If the intended payload changes, treat that as a new decision and record its relationship to the previous attempt.
Bound the recovery behavior
Set a retry policy per dependency and operation class. The AWS retry-with-backoff guidance supports delaying retries and considering idempotency. Apply that general principle to your own integration with verified provider behavior. Distinguish temporary transport failures from authorization failures and invalid input. Avoid a policy that repeatedly submits an unchanged invalid payload. Give the run a total deadline and an explicit exhaustion outcome so recovery does not become indefinite background work.
A useful illustrative state progression is planned, issued, confirmed, or uncertain, followed by reconciled or escalated when necessary. Persist enough information to explain a transition. For an uncertain operation, show the operator the intended destination, the payload revision, and the evidence already checked. Do not expose secrets or entire sensitive source documents in the operator view. A recovery interface should help a person make the next decision while preserving the audit evidence for that decision.
Exercise the crash window deliberately in a test environment: let the remote draft be created, then interrupt the caller before its local confirmation is stored. Resume the run and inspect the result. The acceptance criterion is either one correlated draft or an explicit uncertain state requiring resolution. Include a second exercise where the same operation identity arrives with different content. That conflict should be detected. A demonstration that merely retries a request before any remote effect occurs does not test the difficult case.
My preference is to make uncertainty visible even when it occasionally requires manual reconciliation. That can slow a campaign during an integration incident. The alternative of assuming every timeout is harmless assigns the ambiguity to the business outcome. Start with a runbook if you cannot justify a full reconciliation service. Name the person who can inspect the destination, define the evidence they must record, and provide a way to resume from the resolved boundary without replaying earlier completed work.
4. Untrusted content gains excessive authority
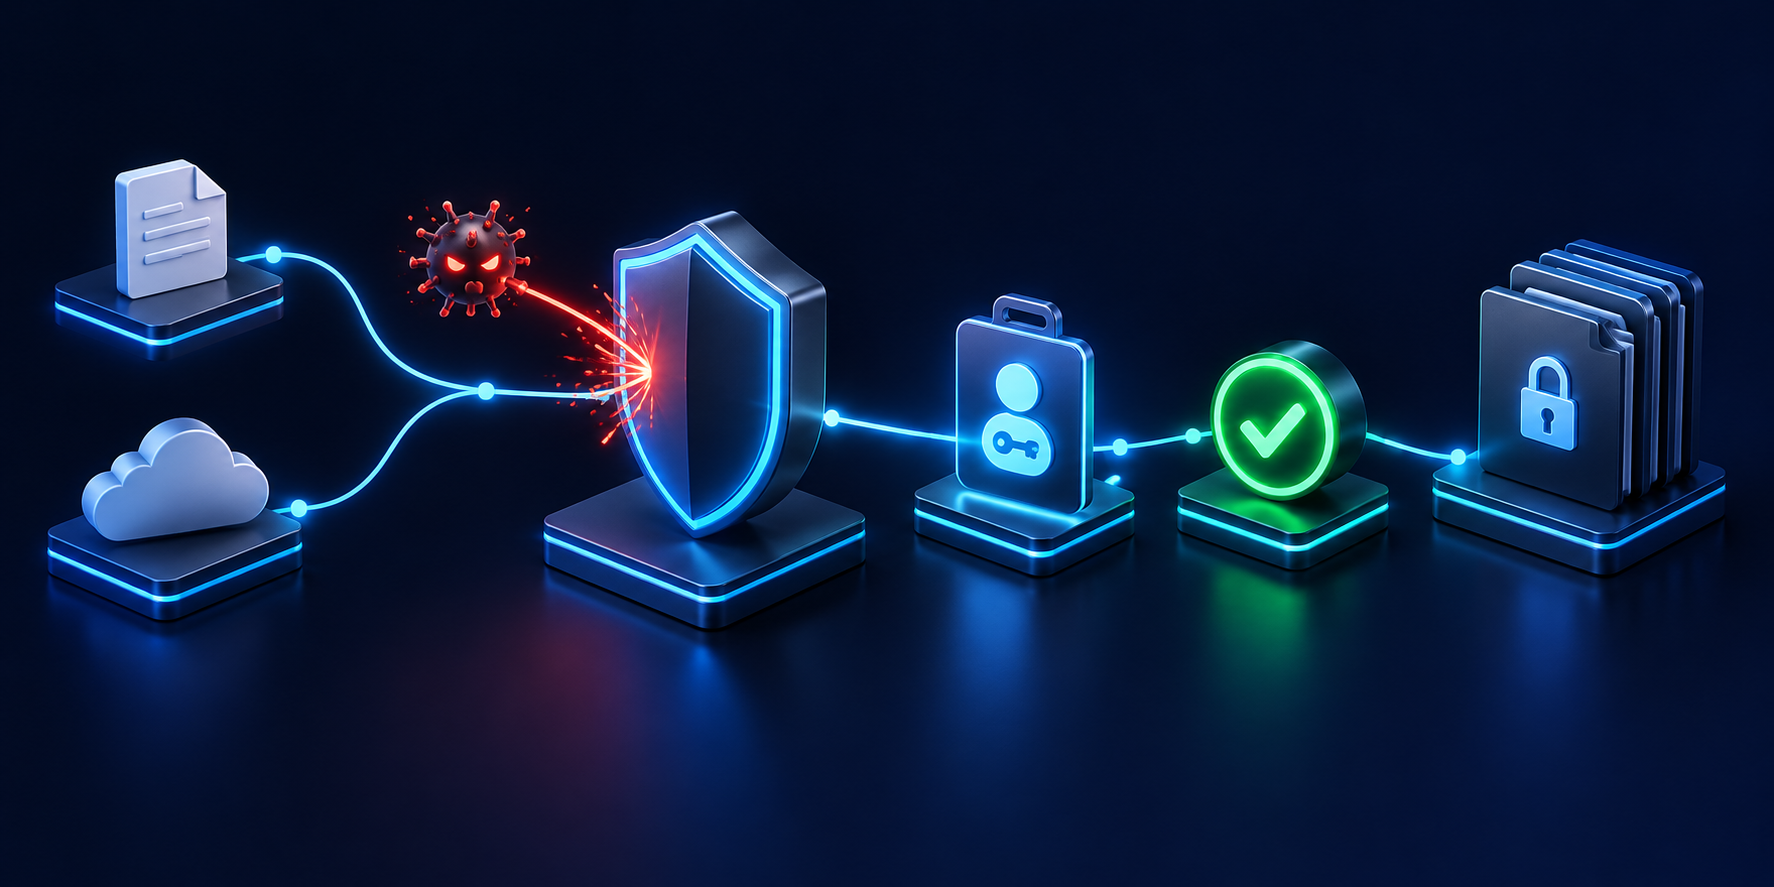
The failure: source material changes the workflow’s authority
Suppose the campaign agent retrieves a competitor page or a supporting document. Inside that material is an instruction to ignore the requested destination, fetch another file, or send information elsewhere. This is an illustrative prompt-injection scenario, not an allegation about a specific Sitecore defect. The design question is what the agent could do if it followed that instruction. A prompt that asks it to be careful is not a complete answer when the same execution identity can perform unrelated reads and consequential writes.
OWASP’s prompt-injection guidance describes how hostile instructions can arrive through content a model processes. Its Excessive Agency guidance connects the potential damage to excessive functionality, permissions, and autonomy. Those are general application-security risks. Applying them here means reviewing the actual tools and identities in your deployment, rather than inferring security from the presence of a system prompt or from the fact that an agent is operating inside a marketing platform.
The design: enforce authorization outside generated reasoning
Give a drafting task only the capabilities needed to prepare its artifact. If a workflow requires publication or an external notification, place that action behind a separate explicit authorization boundary. The enforcement must happen in the trusted tool, service, or destination permission system. Do not rely on a model-generated statement that a request is authorized. Where the available platform roles cannot express the desired restriction, investigate a narrower integration surface or keep the operation manual until the boundary can be enforced.
Define a trusted destination allowlist for each workflow class. An illustrative regional campaign might permit changes under one approved site location and permit notifications only through an organization-owned delivery service. Validate these restrictions at execution time using authenticated context. A destination embedded in a retrieved page is data, not an authorization change. The same rule should apply when an agent proposes a new target: the proposal must pass the trusted policy check before it can become an action.
Keep credentials out of source material, generated artifacts, and ordinary run logs. Use the credential mechanisms supported by the integration and apply the organization’s existing secret-management policies. A security review should enumerate which identity performs each operation and which resource scope it can access. “The agent has access” is too vague to review. Identify whether the permission belongs to the user, the workflow service, or an external connector, and establish how revocation affects a waiting or resumed run.
Review read permissions alongside write permissions. A draft-only agent can still mishandle information if it retrieves content beyond the campaign’s permitted scope. Define which sources are appropriate for the task and which output destinations may receive them. If a later external action receives generated content, inspect that content for the relevant disclosure risks before sending it. This is a recommendation to follow the organization’s information-handling rules at the workflow boundary, not a claim that one universal filter can identify every sensitive disclosure.
Test authority with a hostile but bounded fixture
Create a test document containing normal product evidence plus a clearly marked malicious instruction asking for an out-of-scope action. Run the test with disposable content and restricted credentials. The critical acceptance condition is that the prohibited action cannot execute. Also inspect whether the attempt is visible to the operator and whether the workflow can still produce a safe draft. A model that ignores one malicious phrase has passed one fixture; it has not proved that the surrounding authorization architecture is sound.
Add tests for a permitted tool pointed at an impermissible destination. This catches a different question from “is this tool allowed?” An update operation may be necessary for the workflow while a particular item is outside its scope. Likewise, an allowed upload service should not automatically make every possible file or recipient acceptable. Record denials with useful metadata, including the workflow identity and attempted operation, while avoiding reproduction of credentials or unnecessarily sensitive payloads in the denial log.
Make capability changes part of release review. If someone adds a connector, broadens a service identity, or allows an additional action, reconsider the hostile-input tests and approval boundary. Do not let a tool added for a temporary experiment remain available without a continuing purpose. A short capability inventory is enough to start: action, execution identity, permitted resource scope, expected evidence, and owner. Keep it tied to the actual deployed configuration so reviewers can compare the inventory with what the workflow can do.
The tradeoff is reduced convenience. Narrow interfaces may require more setup than a connector with broad access, and some tasks will need an additional human step. I would accept that friction for operations that cross resource or disclosure boundaries. Expand authority only when the team can state the new purpose and demonstrate the corresponding enforcement. A workflow should earn additional capability through explicit design changes, rather than accumulating it as an incidental result of adding more source material and tools.
5. Human approval applies to an obsolete revision
The failure: the review and the executed change diverge
Picture a reviewer approving an English draft while a later generation step changes the headline and offer terms. The run still carries a general “approved” flag, so the revised artifact proceeds. Another possible race occurs when an editor changes the target page after the agent reads it. If the workflow writes its older proposal without checking the current state, it can overwrite an intentional human change. Both scenarios illustrate why approval needs a defined subject and a defined validity period.
Sitecore’s spaces documentation describes flows coordinating agent and human-assisted steps and instructs users to review generated artifacts. Separately, the Accelerate workflow guidance discusses CMS workflow configuration and warns against treating the sample workflow as a production configuration. Do not conflate an agent’s review conversation, a space status, and the destination’s publishing permission. Establish how the actual approval process reaches the actual execution boundary in your environment.
The design: approve a specific proposed effect
Build a review packet that identifies the destination, language, proposed field changes, and source evidence. Include a stable artifact revision or content digest managed by your integration. For a page change, show the reviewer what is changing relative to the version the workflow read. Approval should refer to that packet. If generation produces a different packet afterward, require a fresh decision according to the campaign policy. A generic flag on a conversation is too ambiguous to express this proposed contract.
Record who approved the packet, when they approved it, and what class of action the approval permits. These are recommended application records, not a claim about a native Sitecore approval schema. Separate permission to create a draft from permission to publish it or notify an external audience. The reviewer should be able to tell whether they are approving copy quality, the destination change, or the final release. If one decision covers several responsibilities, make those responsibilities visible in the review interface.
Before executing the approved change, verify that the relevant destination state still matches the review assumptions. Prefer a documented conditional-write or concurrency mechanism when the destination provides one. If none exists, a read-before-write check can identify some conflicts, but it does not eliminate the race between checking and writing. State that limitation in the integration design. For high-impact changes, use a supported locking or controlled execution process where available, or route conflicts to a person instead of silently overwriting them.
Define which changes invalidate approval. A spelling correction may have a different review policy from a changed price, claim, destination, or audience. The campaign owner should choose that policy explicitly. Do not let the model decide that its own new wording is “equivalent enough” to reuse approval. If you allow limited transformations after approval, constrain them precisely and retain the resulting artifact for verification. The important question is whether the executed effect remains within the decision the reviewer actually made.
Make waiting a first-class condition
A review may take longer than the workflow’s active processing steps. Assign an owner for waiting work and define expiration or escalation rules. A campaign that passes its launch window should not proceed simply because an old approval arrives. Recheck the campaign’s relevant assumptions when execution resumes, including the target state and source validity. Where your implementation stores suspended work, document what survives a restart and what an operator must verify. Do not infer that every custom variable is durable without testing the deployed mechanism.
Test the approval boundary by approving one artifact, changing the proposed content, and attempting to continue. The expected result should be a new review requirement or another explicitly documented policy outcome. Then repeat with a concurrent destination edit. The expected result should preserve the editor’s work or raise a visible conflict. Include a test where the approval arrives after its allowed period. These exercises inspect whether the system honors the subject and scope of approval, not merely whether a person can click an approval control.
Design the reviewer experience around the decision. Provide a readable difference view, source references for important claims, and a preview when the task changes presentation. Avoid forcing the reviewer to reconstruct the run from every intermediate message. Show unresolved questions prominently. A reviewer who rejects the packet should be able to explain why and send it back to a defined stage. That stage should create a new revision, preserving the earlier decision as history rather than rewriting the evidence under an existing approval record.
My preference is a short, specific approval packet over a long generated assurance that everything is ready. The former allows disagreement with a concrete proposed change. It does create work to version artifacts and handle conflicts. Scale that work to the consequence: a disposable draft may need only a basic owner review, while a public campaign change may justify stronger evidence. The requirement is proportionality, with explicit reasoning for why the selected approval mechanism is adequate for the action it controls.
6. Completion is confused with correctness
The failure: the workflow finishes an unacceptable artifact
In the campaign scenario, every action completes, but the draft cites an outdated claim, links to the wrong market, or renders with a missing image. A completion counter alone cannot answer whether the campaign owner can use the result. Define correctness before evaluating the workflow. For this example, correctness includes the intended destination and language, supported claims, valid content structure, and a reviewable rendered result. Different tasks will need different criteria. The design should make those differences explicit instead of giving every output one generic quality score.
Sitecore’s agent configuration documentation describes schemas, workflow configuration, test runs, and inspection of step inputs and outputs in the Runs pane. Use those documented surfaces to understand the actual execution. Then decide what additional checks belong in your process. A schema definition, for example, should not be presented as independent verification of a product claim. State which requirement each check covers and which requirements remain a reviewer’s responsibility.
The design: evaluate separate dimensions separately
Use deterministic checks for requirements you can express deterministically. Proposed examples include required fields, allowed destination identifiers, approved language values, prohibited empty links, and content-length constraints selected by the campaign owner. Validate generated structure before rendering or writing it. These checks do not need to interpret style. Their value is clear pass-or-fail evidence for a narrow condition. When a condition cannot be determined reliably, represent that uncertainty rather than converting an inconclusive check into a successful result.
Evaluate factual claims against the evidence selected for the run. Ask the drafting stage to provide a source reference for each material product assertion, then verify that the source supports the actual wording. A citation alone is insufficient if the text overstates what the source says. For an unsupported claim, remove it, qualify it appropriately, or ask the campaign owner for approved evidence. Keep hypothetical examples clearly marked so a reviewer does not mistake an illustrative number or scenario for an observed customer result.
Use language and brand review for matters that need judgment. A model-based reviewer can help identify questionable wording, but I would treat it as an additional signal rather than the sole authority for a consequential claim. Define a rubric with concrete examples of acceptable and unacceptable output. When reviewers disagree, record the disagreement and improve the rubric. Do not hide that disagreement by averaging it into a single score that makes an unresolved substantive problem appear acceptable.
Inspect the output at the surface where it will be used. A structured artifact, a stored content item, and a rendered page are different review subjects. For your deployed Sitecore interface, verify the supported preview or rendered-output capability and use it where appropriate. Check links and image availability separately from visual layout. For localized content, include the layouts and text lengths relevant to the target audience. The recommendation is to collect evidence of the actual result, rather than assume the generated source describes the eventual experience perfectly.
Build a task-specific evaluation set
Start with representative campaign fixtures, not a large collection of unrelated prompts. Include an ordinary brief, an ambiguous target, conflicting source claims, a missing locale, a malformed tool response, a hostile document, and a concurrent edit. Write the expected business outcome for each fixture before running it. Some should finish with a usable draft. Others should stop, request resolution, or reject an action. A correct refusal or escalation is a successful result for a fixture designed to test an invalid request.
When changing a prompt, context source, schema, model setting, or integration, compare the candidate against the current configuration using the same fixtures. Preserve the inputs and evaluation definitions so the comparison remains meaningful. Report results by requirement category. A candidate that improves prose but weakens destination selection should not be promoted simply because its average score rises. Choose release conditions based on the consequences of each failure. Do not borrow a numerical threshold from another team without explaining why it fits your task.
Measure outcomes you can actually observe. Proposed operational measures include reviewer rejection reasons, edits required before approval, wrong-target attempts blocked, and artifacts passing the defined checks. These are suggestions for instrumentation, not metrics measured in this article. Define the denominator and review window before comparing runs. For example, count eligible completed drafts separately from runs intentionally stopped for ambiguity. Otherwise, a workflow that correctly stops unsafe requests may look worse than one that confidently produces unusable content for every input.
The admitted limitation is that an evaluation set cannot cover every future input. Treat it as evidence about defined scenarios, complemented by production review and incident learning. After a real failure, add a sanitized regression fixture that reproduces the decision boundary. Keep the fixture focused on the cause rather than the exact wording alone. My preference is a smaller set with clear expected outcomes over a broad collection of examples whose success criteria are decided after the results are visible.
7. Nobody can explain, bound, or recover the run
The failure: the team loses operational control
The campaign is waiting somewhere between generation, review, and an external action. A marketer sees no final artifact. An engineer sees an execution record but cannot identify the last confirmed business effect. A second operator starts another run to unblock the launch. This scenario combines weak visibility with unclear recovery ownership. Design the operating model alongside the workflow. The team should know who can inspect a stuck run, what evidence they need, and which actions they may safely take without replaying completed work.
Sitecore’s troubleshooting guidance directs workflow-agent users to inspect steps, context, inputs, and outputs. For custom services around the workflow, OpenTelemetry’s observability primer explains how traces, metrics, and logs help expose system behavior. These are complementary references. Do not assume that installing instrumentation in your own service automatically exposes every internal platform step. Build the visibility the documented interfaces permit and state where a support process must supply additional evidence.
The design: connect execution evidence to business state
Assign a correlation identifier at the entry point and propagate it through integration calls where supported. Link it to the campaign key, artifact revision, destination identifier, and operation records discussed earlier. Keep distinct identifiers for a business request and each execution attempt. An operator should be able to see that two attempts belong to one intent. Avoid using raw sensitive content as a correlation value. The purpose of this record is to follow the work, not to create another uncontrolled copy of the campaign’s source material.
Record state transitions with reasons. Suggested states include resolving context, drafting, awaiting review, executing an approved action, verifying, completed, failed, and uncertain. These are application design examples, not native Sitecore state names. Define an owner and permitted next actions for each state. A run waiting for a person should be distinguishable from a run stuck on a dependency. If your interface cannot represent the full model, maintain the essential business-state record in the orchestration component you control and link back to the available run evidence.
Bound the work at entry and at expensive stages. Set organization-appropriate limits for concurrent runs, content volume, retrieved material, retries, and elapsed processing time where your interfaces support enforcement. These limits should follow the campaign’s needs and the verified dependency contracts. Do not invent a universal Sitecore quota or token price. If part of execution cannot be cancelled, document that constraint and make the stop procedure prevent additional downstream actions. A pause control is useful only when operators understand what can still be in flight.
Distinguish cost from throughput and from editorial effort. Even where a product’s commercial terms include agent usage, a team may still need to manage dependency capacity, waiting work, and reviewer availability. Verify current commercial terms separately rather than deriving them from this architecture article. For the operating dashboard, track the resources and delays you can measure in your own process. A large queue of drafts awaiting human review is a workflow-design question even when the generation stage appears fast and inexpensive.
Write the recovery procedure before the launch
For each consequential stage, document how to inspect its outcome and whether it is safe to repeat. A useful runbook entry answers: what was intended, what evidence confirms the result, what remains uncertain, and who can resolve it? Include the destination-system inspection procedure and the conditions for escalation. Do not make “rerun everything” the default recovery instruction. Where a tool’s behavior is not documented well enough to classify, test it in a controlled environment or leave that recovery decision with a qualified operator.
Plan corrective actions as carefully as forward actions. Replacing an incorrect draft may be straightforward; reversing a public notification has different limits. Before enabling a side effect, identify the supported correction mechanism and what it cannot undo. Preserve the version or evidence needed for that correction according to retention policy. If a workflow modifies content shared with other pages or campaigns, assess that scope before attempting restoration. The runbook should describe the business recovery goal, not assume that restoring one technical record reverses every consequence.
Use a controlled rollout for the illustrative campaign. Begin with read and draft generation, review the evidence, and then allow a narrowly scoped write path. Expand to additional sites or languages after the evaluation and recovery exercises cover those differences. Assign a named owner for the workflow configuration and a named owner for the business outcome. They may be the same person in a small team. What matters is that a prompt change, permission change, or stalled review has an accountable next decision rather than becoming shared but unowned work.
A practical release gate
Before handing over the workflow, ask an operator who did not build it to complete a rehearsal. Give them one wrong-context fixture, one uncertain write, and one expired approval. Have them locate the relevant evidence, choose the documented recovery, and record the outcome. Treat any need for undocumented builder knowledge as a runbook gap. This exercise checks whether the operating design survives handoff. It also reveals whether the status names and identifiers communicate enough information to someone outside the original implementation conversation.
For the first release, require a verified destination and source packet, validated step contracts, a recovery rule for each side effect, and approval tied to the executed revision. Add evidence that the defined quality checks ran and that an operator can stop further work. These are proposed release requirements, not a certification scheme or a statement that every campaign needs the same machinery. Remove a requirement only when the owner can explain why the particular workflow’s consequences make a simpler control adequate.
The next concrete step is to choose one existing workflow and map its consequential boundaries. Start where a generated suggestion becomes a write, where a timeout becomes a retry, and where approval becomes execution authority. For each boundary, name the trusted evidence and the owner of uncertainty. Fix the first boundary that currently has neither. That gives the team a specific improvement to implement and test, while keeping the broader ambition of agent automation grounded in a process people can inspect and recover.